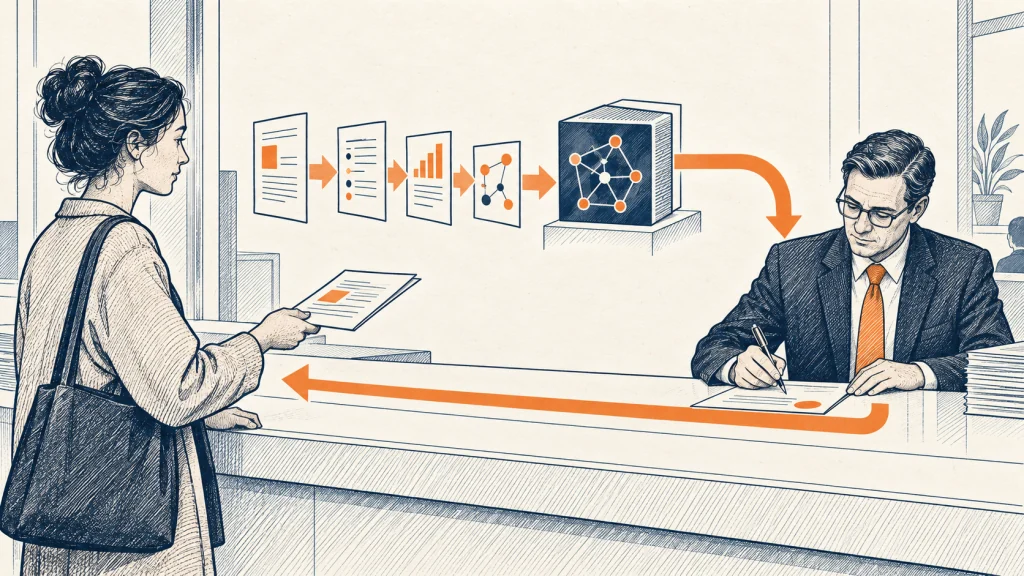
A person applies for assistance, a permit or a document. The answer arrives quickly: they do not qualify. What is missing is an explanation they can verify. Which piece of data decided the case, who checked it, and whom can they tell that it is wrong? This is an imagined situation, but it opens an important question about what we expect from a public administration that uses artificial intelligence.
For Humanophilic, the other side of the story matters too. Used well, AI can free a civil servant from repetition, make relevant documents easier to find and accelerate a procedure. Its value becomes visible when the time released turns into attention for a complex case and when a citizen can exercise a right more easily. The number of cases processed should be read alongside the quality of the explanation and the possibility of correction.
At the centre of this change are the people already working in the institution. A civil servant knows the procedure and, through their work, also comes to know the situations that a form does not describe well. Progress would mean using that knowledge better with appropriate training and an AI tool: finding relevant information, checking proposals and explaining a decision more clearly. If software, new forms and new teams are simply added to an unchanged procedure, the question remains whether we have made the work easier or built another administrative layer.
We are interested here in uses that affect people’s rights, obligations and treatment: who receives assistance, whose application is referred for review, who waits longer, and how a judicial or administrative explanation is produced. We will distinguish between a system that calculates according to predefined rules, a model that recognises patterns in earlier cases, and generative AI that composes text. Each requires a different kind of verification. The selected examples show possibilities and failures; none represents an entire continent or every institution in its country.
More Capable Civil Servants, Better Public Service
Staff training must be part of introducing AI. Learning where to click and how to phrase a prompt is only the beginning. People need to practise on the work they actually do: what may be entrusted to the tool, where to verify its answer, how to recognise an unstated assumption, and when to stop automated processing.
That direction already exists. Canada’s strategy for the federal public service provides for training existing employees, adapted to their role, responsibilities and starting level of knowledge. It is a workforce-development plan; it should not be presented as proof that every civil servant is already trained. Canada — training the existing workforce.
The United Kingdom’s Department for Work and Pensions, DWP, ran a Copilot trial from October 2024 to March 2025, with 3,549 licences allocated. That number does not mean that every employee received the same training or took part in the evaluation. Many learned through independent experimentation, while participants asked for clearer onboarding and training tailored to their tasks. The trial covered central services, excluding Jobcentre staff who work directly with members of the public. The evaluation, based on surveys, interviews and comparison with non-users, describes experience and estimated impact; it does not separately measure how much training itself improves decisions about people’s rights. DWP — trial evaluation.
Brazil’s TRF1 federal court reported training 414 judges and staff in 2025. Colombian judicial guidelines go one step beyond a general call for training: they require learning adapted to the job and the person’s starting knowledge, a practical component, and an assessment of what has been learned. We therefore have evidence that training took place in one case and prescribed requirements in another. Those sources still do not tell us how much better employees become at finding errors after the training. Training is a necessary condition for responsible work, but its effectiveness remains to be measured. A trained official cannot single-handedly repair an unlawful criterion, an unsuitable model or understaffing; changes to rules, tools and the organisation of work are also needed. TRF1 — Sinergia programme, Colombian guidelines, Article 13.
We therefore propose a practical competence test: give an official a case in which an AI proposal contains an incorrect fact, a lost qualification or an inappropriate category. Can they recognise the problem, return to the source and justify the correction? That work requires time, access to documents and the authority to reject the proposal. Without those conditions, a signature may become merely a formal confirmation of the system’s work.
Responsibility should follow real control. The civil servant reviews the case; management provides training and working conditions; the institution governs the choice of system, its use and its correction. That is our criterion of good governance, while specific legal liability is determined under the applicable law. The technical team should support the existing service. Not every routine action needs to wait for a new human signature, but the importance of the decision and the severity of a possible error must determine how much review is required.
Three Sentences, Three Pages, Then Three Sentences Again
Imagine an engineer who writes a report in three sentences. AI turns them into three pages, and a manager instructs another AI to reduce those pages to three sentences. One tool has produced text that another removes. If no necessary, verified information was added along the way, the longer document did not improve the work.
There is a more serious question too: did the final three sentences preserve the original meaning? “We will probably finish on Friday, if the test passes” might be reformulated as “completion is scheduled for Friday”. The condition on which the deadline depends has disappeared. This is an imagined example; it is not a finding about the behaviour of every product or every company.
An AI summary is not a verbatim record: it must be checked for what it omitted, added or presented with more certainty than the source. When reformulated versions travel through several departments, the source must remain available so that meaning can be verified.
Guidance for judges in England and Wales requires the reading of source documents for exactly this reason: AI assistance does not replace direct consideration of the evidence. Good training also includes the ability to recognise when the source is already short and clear enough. Judicial guidance from October 2025, section on responsibility.
When “We Do Not Know” Becomes “We Know”
Generative AI can produce convincing wording without a sufficient factual basis. Among the risks, the US National Institute of Standards and Technology, NIST, describes confident statements of inaccurate content and departures from the supplied input. The linguistic plausibility of an answer is therefore not evidence that an event occurred as the answer claims. NIST — Generative AI Risk Profile, Section 2.2.
An imagined example from a case file shows how much a small change can matter. The source says: “There is no confirmation in the file that the letter was received.” In a retelling, this becomes: “The letter was not received.” In the next summary: “The person was not notified.” The first sentence describes what is missing from the documentation. The second makes a claim about what happened to the letter. The third draws a broader conclusion. None can automatically be inferred from the one before it.
Until further facts are obtained, uncertainty must remain visible. As a verification rule, we propose that a summary distinguish between what is documented, what someone alleges, what is an assumption, and what remains unknown.
An Alert Is Not a Label for a Person
A similar problem arises when a tool sorts statements or people into categories. An isolated word may trigger an alert while the context is lost. “I’m dying of laughter” is not the same as a statement of intent to self-harm. The sentence “I’ll kill you” requires consideration of the circumstances: is it a threat, a quotation, a retelling or an exaggeration? The words alone do not answer that question. These are linguistic examples, not assessments of any particular person.
AI can take account of the context it receives, but it can also miss an important detail. If a “possible threat” is passed to the next stage as a “confirmed threat”, and then as an attribute of the person, the distinction between a signal and a conclusion has been lost. Whether labels are automatically forwarded to other systems depends on the specific application; it should not be assumed for every AI system.
The source, the reason for flagging and the open questions should be preserved with the alert. A trained person should be able to review the category, change or remove it, and ensure that the correction also reaches records to which the incorrect label has already been transmitted. An alert should initiate a review, not predetermine its outcome.
Universal Credit: An Individual Claim, a Statistical Pattern
Universal Credit is a British social-security benefit; here we are looking at the model used for advance-payment applications. Using data from an individual claim, the model estimates the risk of fraud and refers some requests for an advance to a caseworker for review. It learned to classify applications from historical data and recorded outcomes. It receives information about a particular claimant and assesses it against patterns learned from other cases. DWP states that, when training the model, it did not use personal characteristics protected under anti-discrimination rules, apart from age, which affects the amount of payment. Even when such a characteristic is not a direct input, other data may correlate with it. That is a possibility to be tested, not proof that it has occurred here. Not all the data on which the model was developed, nor the weight it assigns to individual variables, are public, with law-enforcement protection cited as the reason. The public therefore cannot reproduce its calculation. Public algorithmic transparency record.
There is also a safeguard in the review process: the caseworker does not see a numerical risk score and does not know that the model selected the case; those claims are mixed with cases selected for comparison. Refusing an advance does not automatically mean refusing the entire Universal Credit entitlement. Even so, additional review is already a consequence for the individual. A pattern may be grounds for checking the facts; by itself, it is not evidence of fraud by a particular claimant. Description of human review.
DWP also reports a benefit: the model is 2.5 times more successful at identifying high-risk advances than random selection from the control group. In its measurement, refusal of an advance after a caseworker’s review counts as a correct referral. Among flagged claims that a caseworker subsequently approves, the median wait for payment is one day longer than for automatically approved claims. These are the department’s own findings, not independent confirmation of overall accuracy or fairness. They nevertheless show the rationale for targeted review instead of demanding additional documents from every claimant. DWP — benefit, waiting time and calculation method.
The same July 2026 assessment records a referral-rate ratio 3.35 times higher for non-British than for British nationals. Among those referred, the ratio of advance-refusal rates between the same two groups was 1.04, with no statistically significant difference. The first figure compares how often cases are reviewed; the second compares the outcome of that review. Neither means that non-British nationals are 3.35 times more likely to commit fraud. The question of false positives on legitimate claims, and of independent scrutiny of caseworker decisions, remains. DWP acknowledges weaker performance for some groups; in that assessment, the retrained model was still awaiting deployment. DWP — 2025/26 performance assessment.
The public data therefore reveal a reason to examine an unequal burden, but do not prove that every referral is discriminatory. The question of stereotyping is addressed by testing the relevance of the data, error rates across groups, and a person’s real ability to rebut an incorrect assumption.
There is also an established European example. The Dutch Data Protection Authority found unlawful and discriminatory processing of nationality in the childcare-benefits system. Among the contested uses was a self-learning risk model that used information about whether an applicant was a Dutch national; high risk scores directed applications to additional review. In 2021, the Tax and Customs Administration was fined €2.75 million for several unlawful processing operations. Human consideration at the end did not remove discrimination in the choice of whom to investigate. The entire scandal should not, however, be attributed to a single model: the harm arose from the combination of data, enforcement policy and institutional conduct. Finding on the risk model, fine decision.
Canada: Who Gets the Faster Route, and Who Is Left Waiting?
Immigration, Refugees and Citizenship Canada, IRCC, uses different tools. For some visa and family applications, rules written by officials and rules derived through machine learning from earlier cases are used to triage applications and check whether straightforward cases meet the requirements of a particular programme. This is not yet a final permission: an officer checks other conditions for entry or residence and makes the decision. IRCC states that these tools neither refuse applications nor recommend refusal. The claim that a human makes every decision should nevertheless be tied to the specific procedure: other rule-based systems can issue a final automated approval, as with some electronic travel authorisations. IRCC — processing applications, register of uses.
How is performance measured? In 2022, IRCC reported an 87 per cent faster assessment of routine visa cases. That is not the same as an 87 per cent reduction in the total waiting time for all applicants. The control described to Parliament that year provided for a daily random sample of ten per cent of straightforward cases. The target was at least 99 per cent agreement by officers with a positive automated assessment of eligibility under the programme. That is a control threshold, not demonstrated overall system accuracy. Agreement with a human also does not reveal an error that both repeat. IRCC — result for routine cases, parliamentary report, page 66.
In 2023, the Auditor General identified a specific weakness in Canada’s spouses and partners programme. Cases with automatically confirmed eligibility were completed in an average of 7.7 months, compared with 9.5 months for those processed manually. Almost all cases involving Haitian nationals followed the manual route. IRCC had neither measured how much of the difference was explained by case complexity nor sufficiently reallocated work to reduce it. This is a documented problem of unequal waiting times and process management, not a finding that the algorithm wrongly refused those people. The institution accepted the recommendation for better monitoring; the promise itself is not evidence that the disparity has been eliminated. OAG — audit, paragraphs 9.57–9.64, IRCC response.
An individual’s position can also be checked after the answer is issued. Since July 2025, refusals of most temporary-residence applications have been accompanied by the officer’s decision notes; permanent-residence refusals have received the same treatment since May 2026, subject to exceptions and the possible redaction of parts of the text to protect information. There is also a route to ask a court to review the lawfulness of a decision. An applicant first seeks leave for judicial review; if leave is granted, the review follows. Yet the public existence of that route does not tell us how many algorithmic errors have been found. The sources reviewed lack a comparable current series showing which tool influenced a case, which error was discovered, how it was corrected, and how long the person waited. Officer decision notes, judicial-review rules, Section 72.
Courts: A Convincing Draft Must Remain Verifiable
AI used to help find case files, compare cases and prepare a working summary can be a sound path towards a more efficient justice system. Brazil’s Supreme Federal Court, for example, uses Victor to classify cases and the Maria tool to support work with content, summaries and drafts. These are described functions; by themselves, they do not prove shorter proceedings overall or better judgments. The benefit arises if less technical work leaves more time for the facts, the parties’ arguments and the verification of sources. STF — uses of AI, September 2025.
Colombia’s T-323/24 judgment shows why the sequence of work matters. In a case concerning the healthcare rights of a child with autism, the judge used ChatGPT after already forming his own reasoning. The Constitutional Court did not find that AI had replaced the judge, but it considered shortcomings in transparency and accountability. It partly upheld the protection of rights and supplemented it in relation to transport. The outcome is therefore not a general licence simply to sign every AI draft, but a requirement that it be possible to show how the judge independently reached the conclusion. Constitutional Court of Colombia — T-323/24.
In another Colombian case, STP21973-2025 of 2 December 2025, a draft conviction prepared with generative AI appeared in the electronic case file before the parties’ closing submissions. The court identified the problem in impartiality and the presumption of innocence: the decision appeared to have been formed in advance, before the proceedings had concluded. This was not a case of software imposing a sentence by itself. AI entered the process at a moment when the draft could compromise the openness of judicial deliberation. Supreme Court — review of case STP21973-2025, subsequent reasoning on the use of AI, page 8.
Brazilian rules on AI in the judiciary explicitly recognise the need for critical analysis and the risk of uncritical acceptance of an automated proposal. The shared question in these cases is how much freedom of judgement remains with the person after a convincingly written draft. Training has value when a judge or official can find the problem, change the conclusion and explain why. Brazilian CNJ Resolution 615, amended text.
India: The Error That Two Levels of Adjudication Failed to Stop
The Indian example shows a concrete consequence of unchecked text. On 2 July 2026, in Pooja Ramesh Singh v Jammu and Kashmir Bank, the Supreme Court of India set aside the decisions of the first-instance and appellate tribunals in insolvency proceedings and remitted the case for a fresh decision. The reasoning contained false claims generated by AI: non-existent cases and invented passages attributed to real judgments. The appellate level did not remedy the problem. Officially published judgment, 2026 INSC 668.
The consequence is real: the decisions did not stand, and the proceedings must be heard again. That does not mean that the Court resolved the underlying debt in advance or established every financial consequence of the error. It shows that the formal presence of people at two levels is not enough if references are not verified. Training for this kind of work must test the source, its legal meaning and its connection with the facts of the particular case, not merely the linguistic plausibility of the draft.
Togo: How the System Chooses Who Receives Assistance
The rural expansion of Togo’s Novissi programme used machine learning in 2020–2021 to direct cash assistance towards poorer people. Satellite data helped select areas, while patterns of mobile-phone use helped assess beneficiaries. From surveys, the model learned which characteristics were associated with poverty, then applied those relationships to other people. It gained a way to estimate who should receive priority, but not direct insight into everyone’s circumstances.
Research published in Nature found 4–21 per cent fewer exclusion errors than with the considered methods of selection by place of residence. An error here means that assistance passes over a poor person whom the selection should have included. Compared with a hypothetical comprehensive social registry, there were 9–35 per cent more such errors. The outcome therefore also depends on the available alternative. The figures measure the selection of beneficiaries, not a reduction in poverty; the study’s authors participated in developing the approach. Nature — programme evaluation.
A person without a phone, or without the ability to register, could be excluded from the process before that assessment even began. A free telephone channel for complaints was available during registration, selection and payment, with complaints monitored daily. The operational report reviewed, however, does not contain enough data to determine how many incorrect poverty estimates were corrected in this way. To assess the individual’s position, we need that result too. World Bank — Novissi.
The story continued through ASTRE, a broader social-protection and registry-development programme. After implementation difficulties, the programme was restructured in April 2026. A World Bank report dated 1 May rated its implementation “moderately unsatisfactory”, while assessing progress towards the development objective more favourably. On 21 April, a new indicator counting people reached by this project’s cash interventions was still at zero. That refers to the new component of programme monitoring, not to historical Novissi recipients. The earlier success should therefore be preserved as the result of a particular programme and period; the performance of its successor should be assessed separately. ASTRE — status as of May 2026.
Australia: When an Average Becomes a Demand to Repay Money
Robodebt is an Australian example of an automated rules-based process. A language model was not needed to create the problem. The programme converted income reported in tax data into a fortnightly average and used it to calculate an alleged overpayment of social-security benefits. Imagine someone who worked for only half the year. Spreading their total earnings across the whole year assigns them income during periods when they did not work. Yet benefit entitlement depends on what they actually earned in the relevant period. The annual total does not prove that. Federal Court — explanation of the process.
That assumption produced a demand for repayment, and the citizen had to find old payslips and show where the calculation was wrong. A good AI tool could make that task easier: organise the documents, compare dates and income, explain the discrepancy and help draft an objection. Such assistance makes sense when people have access to their own case, reliable sources, data protection and a person to contact when the tool is not enough. The institution, for its part, must verify the basis of the debt before demanding money. An easier appeal and a more reliable initial decision should work together.
The financial result was not a saving either. For the period 2014/15–2023/24, using the data and projections then available, the Royal Commission calculated costs of A$971.4 million and estimated savings of A$406.2 million. The difference is a net cost of about A$565.2 million. Implementation and remediation of the programme were included; the broader social harm was not assigned a monetary value. This balance should not be confused with simply adding together debts written off and money refunded. Royal Commission — Chapter 14.
What happened to bureaucracy? The programme automated part of the work, but opened new work elsewhere: additional manual reviews, objections and corrections. The Commission records increased funding because of the greater share of manual and partly online procedures. Victoria Legal Aid reported 21 per cent more Centrelink cases in which it provided assistance in 2016/17, describing the burden created by automated debts. That is not a measure of every additional hour worked across Australia. It nevertheless shows why work should not be measured only at the first department’s desk: the time it saves may later be spent by the citizen, another public body or legal aid. Commission — review costs, Victoria Legal Aid — Annual Report, page 10.
Diella: What Does It Do, and Who Decides?
Albania officially presents Diella as its Minister of State for Artificial Intelligence. Her confirmed initial function is to assist users of the e-Albania portal in accessing services and documents. Behind the ministerial title, however, the specific legal acts must be read. Article 2 of Presidential Decree No. 331 of 12 September 2025 assigns responsibility for establishing and operating the virtual minister to the Prime Minister. The decree itself does not give the software the power to decide an individual case independently in a way that binds people or institutions. Diella’s official page, Decree No. 331.
A government response to an information request, published in the 2025 register, describes the work more precisely: analytical support for collecting, processing and presenting information through services connected to existing government systems. For public procurement, the Prime Minister stated on 11 December 2025 that the competent commission reaches the final result on the basis of information presented by Diella. He also announced the possibility of examining the steps that led to the result. This is the officially described operating model; it is not independent confirmation that every such control is already being carried out. Register of responses, Item 47, description of the public-procurement procedure.
In September 2026, the government was still speaking about building a comprehensive AI-supported public-procurement system. In the sources reviewed, we did not confirm that Diella had independent legal authority to select the winner of a tender, nor did we find a published audit of its decisions and corrections. The practical question remains: what does the commission verify, what can it reject, and what explanation does a participant in the procedure receive? The number of documents processed does not answer that question. Government of Albania, 8 September 2026.
HUDERIA: What Is Assessed, and Is It Mandatory?
HUDERIA is an AI impact-assessment process developed by the Council of Europe, an organisation separate from the European Union. It addresses human rights, democracy and the rule of law. It is not a central European Union software system overseeing every decision. The Committee of Ministers approved the methodology on 26 February 2025, and the accompanying Context-Based Risk Analysis model, COBRA, on 25 February 2026. Both documents are non-binding guidance for public and private organisations. Council of Europe — HUDERIA.
Its value lies in the sequence of questions: where is the system used, whom can it affect, how severe and remediable might the consequences be, what do affected people say, and how will risk be reduced? The assessment covers context, the participation of interested and affected groups, impact assessment, and a mitigation plan. For social assistance, this means that good average accuracy is not a sufficient answer if errors are concentrated among the people who need assistance most.
The EU participated in shaping this approach. Its official note explicitly calls for HUDERIA to remain a voluntary methodology aligned with the approach of the EU Artificial Intelligence Act, the AI Act. Training and work with experts exist through the HUDERIA Academy and Platform, but this is not evidence that all European public administrations already apply the process or publish their results. Council of the EU Note 16537/25, launch of the training and platform.
The AI Act is a separate legal framework. For certain organisations deploying high-risk systems, including public authorities, Article 27 provides for an assessment of possible impacts on fundamental rights, subject to specified exceptions. Under the amended text of July 2026, the relevant rules for high-risk uses listed in Annex III apply from 2 December 2027. HUDERIA can assist an assessment, but it does not in itself confirm legal compliance and does not replace an individual appeal. In Serbia, rights in a particular procedure must be checked against domestic law. AI Act, Articles 27 and 113.
United States: Why a Memorandum Is Not Universal
Through Memorandum M-25-21, the US Office of Management and Budget, OMB, sets rules for AI in the federal agencies to which the document applies. It is not a general law for every private company, state or municipality. Special measures apply to “high-impact” uses in which AI serves as a principal basis for a significant decision about rights or safety. The mere presence of an official does not remove that impact. The document requires impact assessment, testing, oversight and the discontinuation of non-compliant uses; the deadline for baseline measures was 3 April 2026. OMB M-25-21, GAO — overview of requirements.
Three situations must be distinguished. The document does not cover national-security systems, and it provides a specific exemption from high-impact AI obligations for intelligence agencies. Limited pilot uses may qualify for a conditional exemption. Finally, for a particular use, the Chief AI Officer may grant a waiver from a specific requirement if a written assessment shows that the requirement would increase overall risk to rights or safety, or would unacceptably impede work critical to the agency’s mission. Records, annual review, notification to OMB and a public summary within the limits of the law are required. The rationale for this flexibility is the assessment of different risks and operational needs; the justification for any particular exemption still has to be examined. Scope and exemptions in the memorandum.
A requirement that has not been met is a different matter. In February 2026, the US Government Accountability Office, GAO, recorded missing data at the Department of Energy on the start of use and the use of demographic attributes in its AI-system inventory. In March, it found incorrect dates at the Department of Health and Human Services. For the Department of the Interior, which is also responsible for federal lands and natural resources, it stated in November 2025 that the plan described how non-compliant systems should be reported but did not set out how they should be retired. These findings document failures of reporting and planning; they neither confirm an approved exemption nor by themselves prove that a particular dangerous AI system remained in operation. The sources reviewed do not provide a reliable cause for every failure, so it should not be guessed. GAO — tracking recommendations.
The question, then, is not merely whether a document exists, but which obligation applies to the specific system, who signed a waiver, on what basis, and what happened after an error was found.
The Measure Is the Entire Process a Person Goes Through
The most useful comparison begins with a description of the work before AI was introduced. Who did what, how long did the procedure take, and where did errors arise? After deployment, the entire case should be followed, from the application to the decision and any correction. We propose six measures for that assessment:
- Staff capability: after training, can employees reliably review an AI proposal in cases from their own work, recognise a change in meaning, and challenge an incorrect category? The number of people trained is not a sufficient indicator.
- Benefit to the citizen: how long is the route to payment, permission or a reasoned answer; how many times must the same information be submitted, and how much help is available in a complex case?
- Errors, including undetected ones: how many valid applications receive an incorrect label, how many justified claims remain overlooked, and what does an audit of cases that no one appealed reveal?
- Preserved meaning and the possibility of correction: can a reader return from the summary to the source, distinguish a fact from an assumption, and remove an incorrect label from connected records too? How long does the citizen wait, and what consequence do they suffer while the review is under way?
- Differences among people and cases: who is referred for review more often or waits longer? An average acceleration can conceal a group for whom the procedure is slower. Data should be disaggregated with appropriate privacy protection.
- Total work and cost: which unnecessary steps have been removed; how much do the tool, training, maintenance and oversight cost; and how much additional work falls to staff and citizens? Has the time released truly become attention for a complex case?
This is an editorial proposal for assessment, not a universal legal template. Nor does a single figure always have only one meaning. More appeals may indicate more errors, but they may also reflect easier access to an appeal. Fewer appeals may mean better work or a decision that is harder to challenge. The reasons, outcomes and duration must be examined.
From the examples reviewed, we cannot declare any single model of public administration a proven gold standard. There are useful applications, serious failures and rules whose results remain to be tested. It is therefore more important to show what changed in real work than to list the systems purchased.
Who, then, answers to the citizen? In assessing a public service, three questions should be distinguished: who considers and corrects the individual’s case; who oversees the system and remedies repeated errors; and who bears the legal consequences of failure. The first two must have clearly designated people or bodies responsible. The third is determined under the applicable law and on the facts; an official’s signature alone does not settle the liability of the institution, management or supplier.
Our practical demand of an institution is this: the citizen should receive intelligible reasons, a route to correction and a genuine review. To provide that, the civil servant needs knowledge, time, access to sources and authority to challenge a proposal; the institution needs oversight and the capacity to repair the procedure. The purpose of training is for employees to understand a case better with AI and devote more attention to the person. Success is established only when the meaning of information is preserved, unnecessary work is removed, and an incorrect decision can truly be changed.
Sources / Provenance
Nacrt v3.1, dorađen 27. septembra 2026. prema prihvaćenoj uredničkoj oceni. DWP primer uključuje prijavljenu korist i ograničenja, Kanada razdvaja razliku u čekanju od uzroka, obuka ostaje predlog čiji se učinak meri, a završetak razdvaja ispravku predmeta, nadzor sistema i pravnu odgovornost. 46 veza na 42 različita javna izvora. Osnova proveravana 26. septembra, dopune 27. septembra. Pre konačne objave ostaju autorska redakcija i provera aktuelnosti. Nije objavljeno.